Midterm ExamStarted on
Sunday, 06 November 2022, 06:44 PM
Completed on
Sunday, 06 November 2022, 08:15 PM
Time taken
1 hour 30 mins
Grade
77.00 out of a maximum of 100.00
Information
Question i
Exam 1
ITEC 621 Predictive Analytics
Overview:
Learning objective L04 of the MS Analytics program is for the student to: “learn how to: (1)
formulate a relevant business question or hypothesis; (2) search, identify and manipulate the
necessary data to answer that question; (3) evaluate and select the most appropriate analytic
models, methods and tools to analyze the data; and (4) formulate the respective model
effectively and apply the selected methods and tools competently.” (1) and (2) will be evaluated
with the term project; (3) and part of (4) will be evaluated in this exam; and the remaining part
of (4) will be evaluated with the homework.
Allowed and Not Allowed: Students are allowed to have notes, books, etc. They are not
allowed to use any communication devices, including cellphones and tablets. Students can use
their laptop or desktop computers, but only to complete the exam and to access the digital
content provided for this class. Students are not allowed to use the laptop for anything else,
including accessing the web, email, etc.
Material Covered: All lectures and ISLR textbook readings covered in class, up to and including
non-linear models. R coding will not be covered but you need to be able to interpret plots and
other outputs I prepared in R. You are allowed 1.5 hours. There are 4 questions, so you will
need to pace yourself and complete each question in no more than 20 minutes.
General Instructions:
The exam contains 4 questions worth 25 points each. Each question is planned for 20 minutes,
so you should plan to spend no more than that answering each question. You have 1.5 hours to
complete the exam, which gives you a few extra minutes to review your answers. In each
question you are presented with an analytics scenario or concept, followed by a short-answer
question. This scenario will contain one or more of the following: (1) a particular problem to
resolve or business question to answer with predictive analytics (important note: your goal will
NOT be to solve the problem or answer discussion, but to discuss your approach to do that); (2)
an analysis goal (i.e., interpretation, inference or prediction); (3) relevant exhibits, which may
include things like: model summary outputs; plots; distributions; data descriptions/displays;
and/or (4) important concepts covered in class that analytics professionals should know.
There are no questions on R coding, but a few R plots and outputs are included for
interpretation questions. Longer responses will not necessarily earn more credit. More specific,
concise, precise and correct answers will.
Q1
Question 1
The owner of a restaurant chain has hired you to help them predict daily revenues (in
thousands of $) at various restaurant locations. In his opinion, the best predictors for daily
revenue are: weekday (Yes or No, with No representing weekends and holidays), month of the
year (Jan, Feb, Mar, etc., reference re-leveled to Jan), advertising expenditures the prior day,
average price for a 3-course meal (in $), pandemic restrictions (None, Light, Moderate or
Strong; with None as the reference level) and Location (DC, NY, FL, VA and MD; reference releveled to NY). Since revenue and average price are non-negative variables, we logged both in
an OLS model as follows:
Suppose that the predictors listed below are the only ones significant at p < 0.05:
Please interpret each of these effects.
Answer:
The case presented is a multinomial log linear model. Holding everything else constant on
average for each $1k increase in revenue the weekday booking will increase 0.32, price will
decrease by 1.8, the location DC will also decrease by -0.23 which will lead a increase of 0.47
during the month of June while decreasing the Covid restrictions by -.30.
Comments
Comment:
missing effects of categorical variables in relation to their reference level, missing loglinear/log-log interpretations of the coefficients, x&y variables are flipped in the interpretation.
Q2
Question 2
Suppose that you fit an Ordinary Least Squares (OLS) regression model to predict revenues for a
restaurant. You then go to inspect visually for possible violations of OLS assumptions of the
resulting linear model and prepare two residual diagrams shown below. Based on a visual
inspection of these diagrams, which OLS assumption violations would you suspect in each plot?
Please explain the rationale for your answers and refer to the appropriate plot. Also, which test
would you conduct to evaluate these OLS violations statistically? If the tests confirm the
violation of these assumptions, discuss how would you correct for each of them.
Answer:
Based on the fact that a scatter plot and a histogram were used to test the error the following
assumptions could be in violation:
The scatter plot shows a graph with some heteroscedasticy and/or serial correlation and the
histogram is left skewed distribution.
The first OLS assumption that could be in violation is the assumption of a constant variance in
which we have uneven residuals that cause observations with large errors to pull the
regression strongly in both directions, thus increasing the variance. To fix that error we can
run Weighted Least Squares.
The second violation could be the assumption that x and y have a linear relationship if not
some x can be transformed to create a linear model. to correct the issue a nonlinear model
can be run like a polynomial model.
The third violation would be the assumption that Y is continuous, to correct the issue we
could use a generalized linear model, classify the data or run a log regression.
Comments
Comment:
Missing tests to address the OLS violations. Second graph is showing non-normality of the
residuals.
Q3
Question 3
Suppose that you are trying to specify a OLS regression model to predict Dietary Cholesterol (in
milligrams or mg) in commercial packaged dinners (per serving). The predictors of interest (all
in milligrams or mg per serving) are Saturated Fat (SatFat), Dairy, Unsaturated Fat (UnsFat),
Sugar and Carbs. You first try all predictors in the model. You then try a Small model with only
SatFat and Dairy as predictors. You then run a stepwise variable selection between the Large
model and the Null model, which yields a model with only SatFat, UnsFat and Carbss significant
predictors. The respective model and collinearity testing statistics for the respective models
(Condition Index or CI; Variance Inflation Factors or VIFs; etc) are the following:
(*) Denotes significance levels p < 0.05
anova(Small, Stepwise)
p < 0.006
anova(Stepwise, Large)
p = 0.345
a) Which of the 3 models is more biased? Please explain why? Also, indicate which predictor in
that model is likely to be biased.
b) Using the ANOVA tests only, which model would you select? Please explain why.
c) Using the two variable selection methods (i.e., subset selection using ANOVA and Stepwise),
which of the 3 models would you select? Which of the 3 models would you select based on the
collinearity diagnostics? Overall, which is the best model? Briefly explain why.
Answer:
a) The small model is more biased because does not reflect the true effects of the saturated
fat and the other components in the milk; however, anova(Small, Stepwise) p < 0.006 shows
the most significance with that model.
b) The adjusted R square of the large model has more significance with an adjusted Rsquare
of 0.78, but their anova(Stepwise, Large) p = 0.345 does not show significance. I would
choose the Stepwise Model in this case.
c)When looking at the CI of the three models has the highest CI indicating that Large model is
very depended on and has the highest collinearity, so that model would be out as well. The
small model has the smallest CI but it does not reflect the true effects of the saturated fat and
the unsaturated fat in dairy, so that model is out of the questions. I would choose the
stepwise model because 28.1
Essay Writing Service Features
Our Experience
No matter how complex your assignment is, we can find the right professional for your specific task. Achiever Papers is an essay writing company that hires only the smartest minds to help you with your projects. Our expertise allows us to provide students with high-quality academic writing, editing & proofreading services.
Free Features
Free revision policy
$10Free bibliography & reference
$8Free title page
$8Free formatting
$8How Our Dissertation Writing Service Works
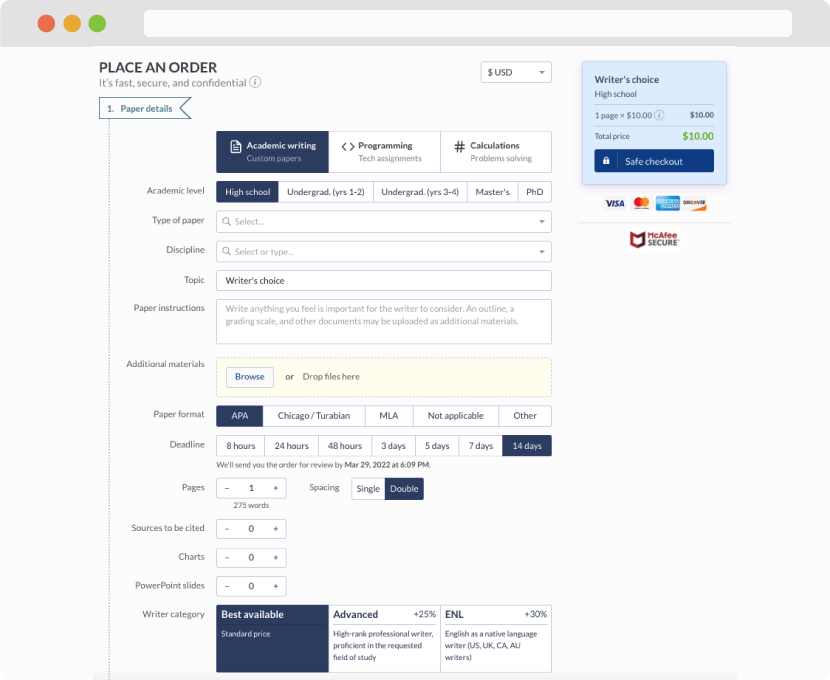
First, you will need to complete an order form. It's not difficult but, if anything is unclear, you may always chat with us so that we can guide you through it. On the order form, you will need to include some basic information concerning your order: subject, topic, number of pages, etc. We also encourage our clients to upload any relevant information or sources that will help.
Complete the order form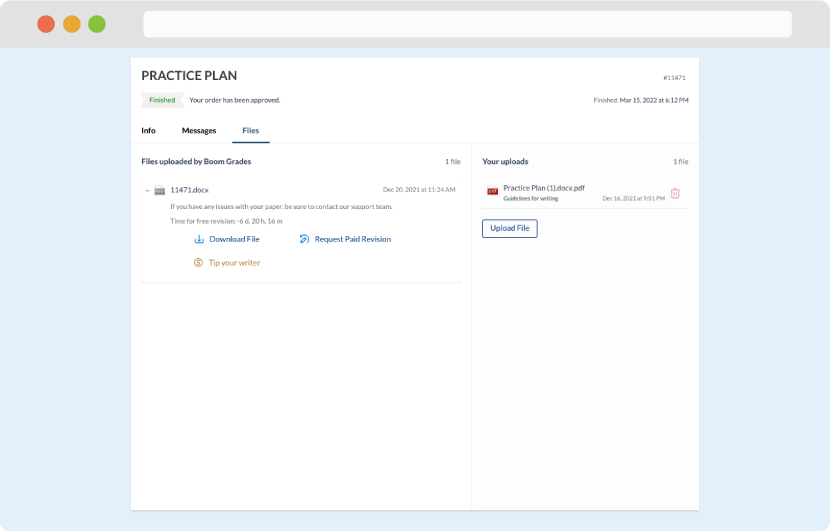
Once we have all the information and instructions that we need, we select the most suitable writer for your assignment. While everything seems to be clear, the writer, who has complete knowledge of the subject, may need clarification from you. It is at that point that you would receive a call or email from us.
Writer’s assignment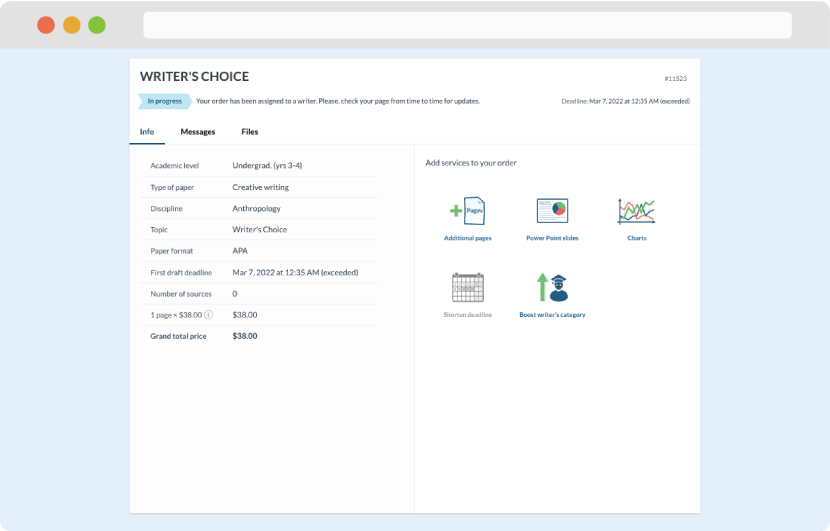
As soon as the writer has finished, it will be delivered both to the website and to your email address so that you will not miss it. If your deadline is close at hand, we will place a call to you to make sure that you receive the paper on time.
Completing the order and download