Continuous Probability Distributions: the
Continuous Uniform and Normal
Distributions
Lesson 5, Lecture 1
1
Recap and Going Forward
• In Lesson 4 we covered some basic probability, random
variables, and discrete probability distributions covering
five specific named distributions.
• In Lesson 5 we will be starting inference, but in this first
lecture we will start with continuous probability
distributions. At this point we will only cover two
distributions:
– Continuous uniform distribution
– Normal distribution
Stat 311 – Cardoso
2
2
1
Continuous Probability Distributions
Tables and bar plots used to graph probability distributions
for discrete RVs are now replaced with smooth curves for
continuous distributions.
pdf for Normal(0,1)
0.3
0.2
0.1
0.0
Relative Frequency
0.4
This is a curve of a
standard normal
distribution, having
a mean of 0 and a
SD of 1.
-3
-2
-1
0
1
2
3
Value of Random Variable
Stat 311 – Cardoso
3
3
Continuous Random Variables
The curve for a continuous distribution is a function of x,
denoted f(x) and may be called one of several terms:
probability density function (pdf), a frequency
function, or a probability distribution.
The areas under a pdf correspond to probabilities for RV
X. The following two conditions are true for probabilities
associated with all continuous RVs:
• 𝑃 𝑎
𝑋
𝑏
• 𝑃 𝑋
𝑥
0
𝑃 𝑎
𝑋
𝑏
Stat 311 – Cardoso
4
4
2
The Continuous Uniform Distribution
• Used for continuous RVs that appear to have equally likely
outcomes over their range of possible values. Suppose for
some continuous RV The height of 𝑓 𝑥 is constant in the
.
interval [a, b] and equals
• Formally, the pdf is written as:
0
xa
1
f x
for a x b
b a
xb
0
• 𝑎 and 𝑏 are parameters of the distribution;
• 𝑿~𝐔𝐧𝐢𝐟𝐨𝐫𝐦 𝒂, 𝒃 or 𝑋~𝑈 𝑎, 𝑏
𝒂 𝒃
𝒃 𝒂
; 𝝈𝑿
• 𝝁𝑿
𝟏𝟐
𝟐
5
Stat 311 – Cardoso
5
The Continuous Uniform Distribution
(continued)
Suppose c
i.e., c 𝑥
𝑥 𝑑 lies within the domain of x;
𝑑 falls within the larger interval 𝑎
𝑥
The probability that x assumes a value within c 𝑥
equal to the area of the rectangle over the interval
c 𝑥 𝑑.
d
d
1
d c
P c x d f x dx
dx
ba
ba
c
c
𝑏.
𝑑 is
The rectangle from c to d is the
area (probability) of interest.
1
ba
a
c
Stat 311 – Cardoso
d
b
6
6
3
Mean of the Uniform Distribution
𝐸 𝑋
𝑥𝑓 𝑥 𝑑𝑥
1
2 𝑏
𝑥
𝑏
𝑎
1
𝑏
𝑥 𝑏
𝑎 2 𝑎
𝑎 𝑏 𝑎
2 𝑏 𝑎
𝑏
𝑎
𝑏
𝑎
1
𝑑𝑥
𝑏
𝑎
2
7
Stat 311 – Cardoso
7
Variance of the Uniform Distribution
Var 𝑋
𝐸 𝑋
𝜇
𝐸 𝑋
2𝜇𝐸 𝑋
𝐸 𝑋
𝜇
𝐸 𝑋
𝜇
2𝜇𝑋
𝐸 𝑋
𝐸 𝑋
𝜇
2𝜇𝜇
𝜇
1
𝑥 𝑏
𝑎 3 𝑎
𝑎𝑏
𝑎
𝑎
𝐸 𝑋
Definition
that is true
for all
distributions
𝐸 𝑋
𝑥 𝑓 𝑥 𝑑𝑥
1
3 𝑏 𝑎
𝑏
𝑎𝑏
3
𝑏
𝑎
𝑥
𝑎
1
𝑑𝑥
𝑏
𝑎
𝑏
𝑎 𝑏
2 𝑏
Stat 311 – Cardoso
𝑏
8
8
4
Variance of the Uniform Distribution
Var 𝑋
𝜎
𝐸 𝑋
𝐸 𝑋
𝑏
𝑎𝑏
3
𝑎
𝑏
2𝑎𝑏
12
𝑎
𝑏
𝑎
12
𝑏
2𝑎𝑏
4
𝑏
𝑏
𝑎
𝑎
12
𝑎
12 Stat 311 – Cardoso
9
9
Functions for the Continuous Uniform
Distribution in R
punif(q, min = 0, max = 1,
lower.tail = TRUE)
qunif(p, min = 0, max = 1,
lower.tail = TRUE)
runif(n, min = 0, max = 1)
Stat 311 – Cardoso
10
10
5
Functions for the Continuous Uniform
Distribution in R (continued)
The new Roosevelt light rail station claims that trains
run every 8 minutes M – F. Assume the time we wait
for a train follows a uniform distribution.
• Find 𝑃 𝑋
3 .
punif(3, min = 0, max = 8) [1] 0.375
• Find 𝑥 such that 𝑃 𝑋
𝑥 = 0.75.
qunif(0.75, 0, 8, lower.tail=FALSE)
[1] 2
11
Stat 311 – Cardoso
11
Functions for the Continuous Uniform
Distribution in R (continued)
Generate 15 random integers from 1 to 12, where each
integer is equally likely.
out pnorm(130, 100, 15)
[1]0.9772499
b
𝑃 90
X
100
> pnorm(100,100,15) – pnorm(90,100,15)
[1]0.2475075
Stat 311 – Cardoso
21
21
Finding Normal Quantiles in R—Examples
Assume that adults have IQ scores that are normally
distributed with a mean of 100 and a SD of 15. For a
randomly selected adult find:
a) Find the value of 𝑥 such that 𝑃 𝑋
𝑥
0.0643
Need the qnorm function.
qnorm(p,mean = 0,sd = 1,lower.tail = TRUE)
qnorm(0.0643, 100, 15, lower.tail = FALSE)
[1] 122.7947
6.4% of adults have IQ scores above about 123 points.
Stat 311 – Cardoso
22
22
11
Finding Normal Quantiles in R—Examples
Assume that adults have IQ scores that are normally
distributed with a mean of 100 and a SD of 15. For a
randomly selected adult find:
b) Find the value of 𝑥 such that 𝑃 𝑋
𝑥
0.4500
qnorm(0.45, 100, 15, lower.tail = TRUE)
[1] 77.20531
45% of adults have IQ scores below about 77 points.
Stat 311 – Cardoso
23
23
Generating Random Normal Observations in R
Use rnorm(n, mean, sd)to generate 𝑛 independent
draws from a normal distribution with a given mean and
sd.
The default is mean = 0 and sd = 1.
rnorm(10, 100, 15)
[1] 95.75461 90.76705 56.50750
[4] 109.44558 115.34097 96.66043
[7] 84.63867 91.76345 117.35281
[10] 99.29715
Stat 311 – Cardoso
24
24
12
Summary
In this lecture, you learned about continuous probability
distributions.
– The continuous uniform and normal distributions
are two examples of continuous probability
distributions.
– Probabilities for the normal distribution can be
found by the pnorm function in R.
– Quantiles for the normal distribution can be found
by using the qnorm function in R.
25
Stat 311 – Cardoso
https://pixabay.com/photos/mountain-rainier-mount-washington-693521/
25
Post to the course Discussion Forum or email me at
tamre@uw.edu if you have questions or comments about this
lecture.
26
13
Rules for Means and Variances
Lesson 5, Lecture 2
1
Recap and Going Forward
• In Lesson 5, Lecture 1 we covered continuous
distributions and two specific distributions, the
continuous uniform distribution and the Normal
distribution
• In Lecture 2 we will cover specific rules for calculating
the means and variances for linear transformations and
linear combinations of random variables.
Stat 311 – Cardoso
2
2
1
Linear Transformations and Combinations of
RVs
A linear transformation of a single random
variable, X, is of the form:
Y a bX, where a and b are constants
A linear combination of random variables, X, Y, . . .
is a combination of the form:
L = aX + bY + …
where a, b, etc. are constants – positive or negative.
Common:
W = X + Y (sum) W = X – Y (difference)
3
Stat 311 – Cardoso
3
Rules for Means
1. Let X be a RV, a and b be constants, and define
𝑎 𝑏𝜇 or
𝑊 𝑎 𝑏𝑋. Then 𝜇
𝑎 𝑏𝐸 𝑋 .
𝐸 𝑊
2. If X and Y are RVs and 𝑊
If 𝑊
𝑋 – 𝑌 then 𝐸 𝑊
𝑋
𝑌, then 𝜇
𝜇
𝜇 .
𝐸 𝑋 –𝐸 𝑌 .
The mean of the sum is the sum of the
means.
The mean of the difference is the difference
of the means.
Stat 311 – Cardoso
4
4
2
Rules for Variances and Standard Deviations
1. Let X be a RV, a and b be constants, and define
𝑊 𝑎 𝑏𝑋. Then,
𝑉𝑎𝑟 𝑎 𝑏𝑋
𝑉𝑎𝑟 𝑎
𝑉𝑎𝑟 𝑏𝑋
𝑉𝑎𝑟 𝑊
𝑏 𝑉𝑎𝑟 𝑋
0 𝑏 𝑉𝑎𝑟 𝑋
𝑏 𝜎
Can also be written as 𝜎
2. If X and Y are independent RVs and define
𝜎
𝜎
𝑊 𝑋 𝑌, then 𝜎
𝑽𝒂𝒓 𝑿
If 𝑊
𝑋– 𝑌, then 𝜎
𝜎
𝑬 𝑿𝟐
𝜎
𝑬 𝑿
𝟐
The variance of the difference is still the sum of
the variances.
𝑽𝒂𝒓 𝑿 𝒀
𝒀 𝟐
𝑬 𝑿
𝝈𝟐𝑾
Also, 𝝈𝑾
𝑬 𝑿
𝒀
𝟐
5
Stat 311 – Cardoso
5
Rules for Variances and Standard Deviations
(continued)
3. If X and Y are dependent RVs having correlation 𝜌,
then
𝑊
𝑋
𝑌; 𝜎
𝜎
𝜎
2𝜌𝜎 𝜎
𝑊
𝑋
𝑌; 𝜎
𝜎
𝜎
2𝜌𝜎 𝜎
The correlation between two independent
RVs is zero.
Stat 311 – Cardoso
6
6
3
Rules for Means—Example
The RV X has 𝐸 𝑋
20 and the RV Y has
𝐸 𝑌
10. Define 𝑊 0.5𝑋 2𝑌. Find 𝐸 𝑊 .
E(W ) 0.5E(X) 2E(Y )
0.5(20) 2(10)
10 20 30
7
Stat 311 – Cardoso
7
Payoff in a Tri-State Pick 3 Lottery—Example
The payoff, X, of a $1 ticket in a Tri-State Pick 3 game is
$500 with probability 1/1000 and 0 the rest of the time.
Calculate the mean and standard deviation of the X.
Calculate 𝜇 and 𝜎
𝒙
𝒑
𝒙𝒑
0 0.999
500 0.001
0
0.5
𝒙 𝝁𝑿 𝟐 𝒑
(0 – 0.5)2(0.999) = 0.24975
(500 – 0.5)2(0.001) = 249.50025
𝜇
$0.5
𝜎
249.75
𝜎
249.75
$15.80
Stat 311 – Cardoso
8
8
4
Payoff in a Tri-State Pick 3 Lottery (continued)
𝒙
𝒑
𝒙𝒑
0 0.999
500 0.001
0
0.5
𝜇
𝒙 𝝁𝑿 𝟐 𝒑
(0 – 0.5)2(0.999) = 0.24975
(500 – 0.5)2(0.001) = 249.50025
$0.5
𝜎
249.75
Calculate the mean winnings.
Define 𝑊 𝑋 1.
𝜇
Then, 𝜇
1
0.5
1
$0.50
9
Stat 311 – Cardoso
9
Payoff in a Tri-State Pick 3 Lottery—Two
Tickets
𝒙
𝒑
𝒙𝒑
0 0.999
500 0.001
0
0.5
𝜇
$0.5
𝒙 𝝁𝑿 𝟐 𝒑
(0 – 0.5)2(0.999) = 0.24975
(500 – 0.5)2(0.001) = 249.50025
𝜎
249.75
Calculate the mean payoff for two tickets:
𝐸 𝑋
𝐸 𝑌
$0.50 $0.50
𝐸 𝑋 𝑌
$1.00
Calculate the standard deviation of the total
payoff: because X and Y are independent, Var(X + Y)
2
XY
X2 Y2 249.75 249.75 499.5
XY X2 Y2 499.5 $22.35
Stat 311 – Cardoso
Not the same as the
sum of individual
SDs—variances of
independent RVs add,
not SDs
10
10
5
Combining Independent RVs for some Common
Distributions
If X and Y are independent normal RVs and W = X + Y,
then
W ~ N X Y , X2 Y2
If W = X – Y, then W ~ N X Y ,
X2 Y2
If X ~ Binomial (n, p) and Y ~ Binomial (m, p), are
independent and W = X + Y, then
W ~ Binomial(n + m, p)
If X ~ Poisson (𝜇 ) and Y ~ Poisson (𝜇 ), are
independent and W = X + Y, then W ~ Poisson(𝜇 + 𝜇 )
11
Stat 311 – Cardoso
11
Example—Travel Times
X = Meg’s travel time is normal with mean 25 minutes
and SD 3 minutes.
Y = Airport time is normal with mean 15 minutes and SD 2
minutes.
Define T = total time to get to the gate. What is the
distribution of T?
If we assume X and Y independent. Then
𝟑𝟐 𝟐𝟐 𝟑. 𝟔
𝑻~𝑵 𝝁𝒕 𝟐𝟓 𝟏𝟓 𝟒𝟎, 𝝈𝒕
If Meg leaves with 45 minutes before flight takes off, what
is probability she will miss her flight?
𝑷 𝑻
𝟒𝟓
𝟏
pnorm(45, 40, 3.6)
Stat 311 – Cardoso
𝟎. 𝟎𝟖𝟐𝟒
12
12
6
Example—Donations Add Up
Fund drive: Three volunteers call potential donors.
About 20% of calls result in a donation, independent of
who called. If three volunteers make 10, 12 and 18 calls,
respectively, what is the probability that they get at
least ten donors?
X = # donors by volunteer 1; binomial 𝑛𝑋 10, 𝑝 0.2
Y = # donors by volunteer 2; binomial 𝑛𝑌 12, 𝑝 0.2
W = # donors by volunteer 3; binomial 𝑛𝑊 18, 𝑝 0.2
What is the distribution of T, the total number of donors?
𝑻 𝑿 𝒀
𝑷 𝑻 𝟏𝟎
𝑾, so T ~ Binomial(40, 0.2)
1 – pbinom(9, 40, 0.2)
𝟎. 𝟐𝟔𝟖𝟐
Stat 311 – Cardoso
13
13
Summary
• Mean of the sum is the sum of the means when
adding/subtracting random variables
• Expected value of a RV multiplied by a constant c, is
𝑐 𝐸 RV
• For independent RVs, the variances add
• Variance of a constant is zero
• Variance of a RV multiplied by a constant, c, is
𝑐
𝑉𝑎𝑟 RV
• The sum or difference of two normal distributions will also
be normal.
• The sum of two or more Binomial distributions with the
same probability of success will also be Binomial.
• The sum of two Poisson distributions will be Poisson.
Stat 311 – Cardoso
14
14
7
https://pixabay.com/photos/mountain-rainier-mount-washington-693521/
Post to the course Discussion Forum or email me at
tamre@uw.edu if you have questions or comments about this
lecture.
15
8
Hypothesis Testing Using Randomization
Lesson 5, Lecture 3
1
Recap and Going Forward
• In Lesson 5, Lecture 2 we covered specific rules for
calculating the means and variances for linear
transformations and linear combinations of random
variables.
• In this lecture we are going to move into the topic of
inference and will start by defining some terms and then
outlining the basic concept of hypothesis testing through
randomization.
Stat 311 – Cardoso
2
2
1
Statistical Inference
• Interest in saying something about a population from a
sample because we cannot observe all individuals in a
population
– For quantitative populations, the location and shape
are described by μ and σ.
– For a binomial population, the location and shape
are determined by p.
Stat 311 – Cardoso
3
3
Types of Statistical Inference
• Estimation
– Estimating or predicting the value of the
parameter.
– “What is (are) the most likely values of μ or p?”
• Hypothesis Testing
– Deciding about the value of a parameter based on
some preconceived idea.
– “Did the sample come from a population with
μ = 5 or p = 0.2?”
Stat 311 – Cardoso
4
4
2
Statistical Inference: Examples
• A consumer wants to estimate the average price of similar
homes in her city before putting her home on the market.
– Estimation: Estimate μ, the average home price in
the city.
• A manufacturer wants to know if a new type of steel is
more resistant to high temperatures than an old type
was.
– Hypothesis test: Is the new average resistance, μN,
equal to the old average resistance, μ0?
Stat 311 – Cardoso
5
5
Statistical Inference and Uncertainty
Whether you are estimating parameters or testing
hypotheses, statistical inference methods allow a
numerical measure of the goodness or reliability of the
inference. Or a measure of the uncertainty of the
inference.
Stat 311 – Cardoso
6
6
3
Statistical Inference in Concept
• If you have access to data on an entire population, say
the opinion of every adult in the United States on
whether they think climate change is affecting their
local community, it is straightforward to answer
questions like, “What percent of US adults think
climate change is affecting their local community?”.
• If you had demographic information on the population
you could examine how, if at all, this opinion varies
among young and old adults and adults with different
political leanings.
Stat 311 – Cardoso
7
7
Statistical Inference in Concept (continued)
• What if you only have access to a sample of the
population?
• What is your best guess for this proportion if you only
have data from a small sample of adults?
• What if you want to test a claim about the population
parameter value?
• These types of situations require that we use our
sample to make inference on what the population looks
like.
Stat 311 – Cardoso
8
8
4
Statistical Inference—Hypothesis Testing
• Statistical hypothesis testing is the process of
making claims about a population based on
information from a sample
• The main logic behind hypothesis testing is to reject a
research claim which is not of interest to validate the
claim of interest
• For example, to show that a new drug for high blood
pressure is better than an older drug, we want to reject
the idea that the two drugs are equally effective at
lowering blood pressure.
Stat 311 – Cardoso
9
9
Statistical Inference—Hypothesis Testing
• Hypothesis testing requires a set of competing
hypotheses
• These competing hypotheses are formulated based on
the research claim
• In this lecture we focus on the use of randomization, to
help you conceptualize the use of the “rare event rule”
• We will define a p-value, which can be thought of as
the degree of disagreement between the data and the
research claim
Stat 311 – Cardoso
10
10
5
From Sample to Population
Image from OpenIntro
Stat 311 – Cardoso
11
11
Blood Pressure Drug Example
• 200 adults with high blood pressure volunteered to
participate in an experiment to test the effect of the new
blood pressure drug
• 100 adults were randomized into the new drug group
and 100 were randomized into the control (old drug).
• Systolic pressure was measured at the start of the
experiment and again after two months. The response
variable was the proportion of participants that had a
decrease of 10 points after two months.
• Our research hypothesis is that the new drug will have a
higher proportion of participants with a meaningful
decrease in systolic pressure compared to the old drug.
Stat 311 – Cardoso
12
12
6
Blood Pressure Drug Example (continued)
Reduction in
New Drug Old Drug
Systolic Pressure
77
82
10 points
23
18
10 points
We can estimate the sample proportions for a
meaningful decrease in systolic pressure for both groups
0.23 and 𝑝̂
𝑝̂
0.18
How do we compare these two statistics to make a
statement for the new drug compared to the old drug?
13
Stat 311 – Cardoso
13
Blood Pressure Drug Example (continued)
𝑝̂
0.23 and 𝑝̂
0.18
Let’s go back to our research hypothesis and methods
• We hypothesized that the new drug would have a higher
proportion of participants with a meaningful decrease in
systolic pressure compared to the old drug.
• One way to think about his is to calculate the difference
𝑝̂
𝑝̂
0.18
0.23
0.05
Stat 311 – Cardoso
14
14
7
Vocabulary—Defining Testable Hypotheses
To show that a new drug for high blood pressure is better
than an older drug, we define our competing hypotheses
• Null hypothesis (𝐻 —the claim that nothing is interesting.
For example, there is no difference in the proportion of
participants with meaningful decreases in systolic pressure
𝑝 →𝑝
𝑝
0 .
𝑝
• Alternative hypothesis (𝐻 —the claim that corresponds to
the research hypothesis. For example, the new drug results
in a higher proportion of meaningful decreases in systolic
pressure 𝑝
𝑝 →𝑝
𝑝
0 .
The goal, almost always, is to have evidence to disprove the
null and conclude that the alternative is true.
15
Stat 311 – Cardoso
15
The “Big-5” Parameters and Their Statistics
Name
Single Mean
Difference between two
means, independent
samples
Difference between two
means, dependent samples
Single Proportion
Difference between two
proportions, independent
samples
Parameter Statistic
𝜇
𝑥̅
𝜇
𝜇
𝑝
Stat 311 – Cardoso
𝑥̅
𝑥̅
𝜇
𝑑̅
𝑝
𝑝̂
𝑝
𝑝̂
𝑝̂
16
16
8
Sampling Variability
We observed 𝑝̂
𝑝̂
0.18 0.23
0.05
but imagine running the experiment again with a new
sample of 200 participants.
What should we expect?
• The values of 𝑝̂ will vary with each run of the
experiment.
We need to understand what we would expect to see due
to random sample variability, or how much the 𝑝̂ values
would vary from experiment to experiment if the drugs
did not produce different results.
Stat 311 – Cardoso
17
17
The Null Distribution
• We can build a distribution of differences in
proportions assuming the null hypothesis (no
difference between the drugs) is true.
• The null samples consist of randomly shuffled blood
pressure readings (baseline minus end of two months)
so that the samples don’t have any dependency
between drug administered and a meaningful decrease
( 10 points).
• This will allow us to determine if our observed results
are inconsistent with the null hypothesis.
Stat 311 – Cardoso
18
18
9
Data Subset
Treatment GE10
New
1
New
1
New
1
New
1
New
0
New
0
New
0
Old
1
Old
1
Old
0
Old
0
Old
0
Old
0
Old
0
Stat 311 – Cardoso
19
19
Generating the Null Distribution in R
PermsOut %
# added call to rep_sample_n
rep_sample_n(size = nrow(BP), reps = 1000,
replace = FALSE) %>%
mutate(BP_perm = sample(GE10)) %>%
# added replicate to group_by
group_by(replicate, Treatment) %>%
summarize(prop_BP_perm = mean(BP_perm),
prop_BP = mean(GE10)) %>%
# Old – New
summarize(diff_perm = diff(prop_BP_perm),
diff_orig = diff(prop_BP))
PermsOut
Stat 311 – Cardoso
20
20
10
Null Distribution from Randomization
> PermsOut
replicate
1
2
3
4
.
.
.
1000
diff_perm
-0.05
-0.01
0.05
0.03
diff_orig
-0.05
-0.05
-0.05
-0.05
0.01
-0.05
Stat 311 – Cardoso
21
21
Dot Plot of Null Distribution
p1 = diff_perm))
This gives 259 or 0.259 or about 26%.
• About 26% of the null statistics are more extreme than the
difference which was observed from the original sample.
• In conjunction with the dot plot, this gives evidence that
the data are consistent with the permuted distribution.
We have no evidence that the rates of decrease in systolic
pressure differ between the new and old drugs.
Stat 311 – Cardoso
24
24
12
The p-value
How extreme are the observed data?
• We say that the p-value is 0.259
• The p-value is the probability of seeing our sample
observed difference or something more extreme in the
direction of the alternative, given the null hypothesis is
true.
𝐻 :𝑝
𝑝 →𝑝
𝑝
0
𝐻 :𝑝
𝑝 →𝑝
𝑝
0
In this example, the p-value (0.259) is the probability of
observing a difference of 0.05 or more assuming the
proportion of people with at least a 10-point drop in blood
pressure does not vary across the new and old drug.
Stat 311 – Cardoso
25
25
More Interpretation
• In our calculations for the BP data, the observed statistic
was consistent with the null statistics based on
permutations.
• 259 of the 1000 permutations were smaller than the
original sample difference.
• There is no evidence that the data are inconsistent with the
null hypothesis. That is, if the drugs did not yield different
responses, we would be likely to get data like those
observed.
Stat 311 – Cardoso
26
26
13
More Interpretation (continued)
• It is possible that the true difference in the proportions is in
fact 5% (not 0), and surely our data would be consistent
with that population as well.
• A declaration of evidence or no evidence is based on the
p-value. We declare evidence in favor of the alternative
when the p-value is small.
• This does not mean that we know for sure that the two
drugs do not play different roles in decreasing systolic blood
pressure.
Stat 311 – Cardoso
27
27
More Interpretation (continued)
• The logic of inference allows us only to reject null claims.
The process does not allow us to have certainty in the null
hypothesis being true.
• We fail to reject the null hypothesis: There is no
evidence that our data are inconsistent with the null
hypothesis. There is no evidence of a difference between
the proportion of meaningful blood pressure decrease
between the new and old drug.
Stat 311 – Cardoso
28
28
14
Summary
In this lecture we introduced the concept of hypothesis
testing using randomization.
• We used permutations of the labels between the new and old
drug to construct a distribution of many possible outcomes
from the experiment if there was no difference between the
groups
• This is termed the null distribution. Our statistic was
𝑝̂
𝑝̂
29
Stat 311 – Cardoso
29
Summary (continued)
• We also calculated this statistic for our sample data and then
compared our observed statistic with what we would expect
to see under the null distribution of no difference
• We computed the p-value as proportion of cases from the
null distribution that are more extreme than our observed
statistics
• Since our p-value was large (not
the null hypothesis.
5%), we failed to reject
• We concluded that there was no evidence that the new drug
had a higher proportion of people with reduced blood
pressure compared with the old drug.
Stat 311 – Cardoso
30
30
15
http://www.sfu.ca/sfunews/files/summer2007/endangered.jpg
Post to the course Discussion Forum or email me at
tamre@uw.edu if you have questions or comments about this
lecture.
31
16
Sampling Distributions
Lesson 5, Lecture 5
1
Recap and Going Forward
• In Lecture 4, we introduced the confidence intervals
by constructing a bootstrap distribution of sample
proportions using the original sample, and then
finding the lower and upper bounds of the
distribution for the middle 95% of 𝑝̂ values.
• In this lecture we further develop the idea of
sampling distributions for some common statistics.
The methods in this lecture will allow us to apply
inferential methods using these common statistics
without having to use randomization or
bootstrapping.
Stat 311 – Cardoso
2
2
1
Sampling Distributions—Statistics as RVs
Previously Defined Terms
• Parameter—a numerical descriptive measure of a
population that is fixed for a given point in time.
• Sample statistic—a numerical descriptive measure of a
sample; calculated from the observations in a sample.
A couple of important things to note:
1. Sample values are measurements or observations of RVs
the value for a sample statistic will vary in a random
manner from sample to sample.
2. Thus, sample statistics are RVs because different
samples can lead to different values for the sample
statistics.
Stat 311 – Cardoso
3
3
Sampling Distributions (continued)
Sampling distribution (of a sample statistic)—the
distribution of possible values of a statistic for repeated
samples of the same size from a population.
• The concept of a sampling distribution is important in
statistical inference where we want to make
conclusions about population parameters based on
sample statistics.
• To make conclusions about population parameters, we
need to know something about how the sample
statistics are distributed.
Stat 311 – Cardoso
4
4
2
Sampling Distributions (continued)
Some sample data that we will be used for the content in the
next few slides. For illustrative purposes, we will assume that
these data are a population, and we will be drawing samples
from the 198 total data points.
80
60
40
Min: 0.00000
1st Qu.: 78.25000
Mean: 81.00518
Median: 84.00000
3rd Qu.: 91.00000
Max: 99.00000
Total N: 198.00000
NA’s :
4.00000
Std Dev.: 18.34231
20
0
0
11
22
33
44
55
66
Midterm
Stat 311 – Cardoso
77
88
99
5
5
Sampling Distributions (continued)
This table shows the means for six samples that were drawn
from the population of midterm scores. Each column
represents a different sample size.
Sample Mean
Sample
n = 10
n = 20
n = 30
n = 50
1
86.89
83.05
84.45
82.22
2
77.40
73.16
82.76
82.90
3
85.90
78.68
84.30
82.06
4
79.90
73.15
82.14
81.06
5
86.40
81.10
80.31
78.51
6
80.40
82.61
81.47
82.52
Stat 311 – Cardoso
Columns represents a fixed
sample size and shows
mean scores for six
different samples.
Blue cell is one mean score
for a sample of size 20.
Purple cell is one mean
score for a sample of size
50.
Although close, notice that
none of the means are the
same.
6
6
3
Sampling Distributions (continued)
n = 20
0
0
50
50
100
100
150
150
200
n = 10
60
70
80
90
65
70
mean10.out[1:1000]
75
80
85
90
mean20.out[1:1000]
n = 50
0
0
50
50
100
100
150
200
150
250
n = 30
70
75
80
85
mean30.out[1:1000]
74
76
78
80
82
84
86
88
Each histogram based on the
means for 1000 individual
samples from the population of
midterm scores. Each
histogram has means
calculated from different
sample sizes
(n = 10, 20, 30, or 50).
Notice how the distributions
become more symmetric as
sample size is increases. Also,
each distribution is centered
around the true (population)
midterm score of about 81.
mean50.out[1:1000]
7
Stat 311 – Cardoso
7
Sampling Distributions (continued)
Same four sampling distributions for mean midterm scores
from the previous slide, with x- and y-axes scaled the same.
n = 10
n = 20
n = 30
n = 50
Stat 311 – Cardoso
In addition to more
symmetric shapes with
increasing sample size,
notice the decrease in
the variability (smaller
SD) with increasing
sample size.
8
8
4
Sampling Distributions (continued)
Let’s repeat the exercise, but this time let’s start with a
different distribution.
Start with what distribution?
0.10
p(x)
0.08
0.06
0.04
0.02
0.00
0
2
4
6
8
10
x
9
Stat 311 – Cardoso
9
Sampling Distributions (continued)
Sampling Distributions for means from U(0,10)
0.3
n=5
0.4
n = 10
0.3
0.2
0.2
0.1
0.1
0.0
0.0 1.3 2.6 3.9 5.1 6.4 7.7 9.0
0.0
0.0 1.3 2.6 3.9 5.1 6.4 7.7 9.0
0.6
0.8
0.5
n = 20
0.4
0.3
0.2
0.1
0.0
0.0 1.3 2.6 3.9 5.1 6.4 7.7 9.0
n = 30
0.6
Four histograms for the
means from samples from
the uniform (0,10)
distribution. All the
histograms are shown with
identical x-axis scales.
The distributions tend to
be unimodal, symmetric
and the variability
decreases with increasing
sample size.
The histograms appear to
be centered around the
0.2
population mean value of
0.0
0.0 1.3 2.6 3.9 5.1 6.4 7.7 9.0 5.
0.4
Stat 311 – Cardoso
10
10
5
Sampling Distributions (continued)
Let’s repeat the exercise, for one last starting distribution.
The graph to the left
shows the distribution
X ~ Lognormal , Y log X ~ N ,
for 1000 observations
500
from a lognormal
1
2
distribution with mean
EX e 2
400
= 0 and SD = 1.
This distribution is
unimodal and heavily
right-skewed.
300
200
100
0
0.0
2.3
4.5
6.8
9.0 11.3 13.5 15.8 18.0 20.3 22.5
The expected value or
mean for this
lognormal distribution
is about 1.65.
11
Stat 311 – Cardoso
11
Sampling Distributions (continued)
n=5
n=10
0.6
0.4
0.3
0.4
0.2
0.2
0.1
0.0
0.0 0.9 1.9 2.8 3.8 4.7 5.7 6.6 7.6 8.5
n=20
0.8
0.6
0.4
0.2
0.0
0.0 0.9 1.9 2.8 3.8 4.7 5.7 6.6 7.6 8.5
Four histograms for the
means from samples from
the lognormal(0, 1)
distribution, for sample
sizes of 5, 10, 20, and 30. All
the histograms are shown on
with identical x-axis scales.
0.0
0.0 0.9 1.9 2.8 3.8 4.7 5.7 6.6 7.6 8.5
The distributions of the
means tend to become
n=30
symmetric with increasing
0.8
sample size. Further, the
variability decreases with
0.6
increasing sample size. Also,
0.4
the histograms appear to be
0.2
centered around the
0.0
0.0 0.9 1.9 2.8 3.8 4.7 5.7 6.6 7.6 8.5
population mean value of
1.65.
Stat 311 – Cardoso
12
12
6
Sampling Distributions (continued)
• Many common, practical problems involve estimating
mean values from samples; interest is really in making
an inference about the mean, 𝜇, of some population.
• What do we know: the sample mean, 𝑥̅ , is often a
good estimator of 𝜇.
• Example: Midterm exam scores—we considered the
class data to represent the population.
• Let’s look again at histograms for 𝑥̅ based on n = 10,
20, 30 and 50 samples (shown on the next slide).
13
Stat 311 – Cardoso
13
Sampling Distributions (continued)
0.10
n = 20
0.06
n = 10
0.0
0.0
0.02
0.02
0.04
0.06
The normal probability distribution (orange lines)
approximates the computer-generated sampling distributions
very well.
60
70
80
90
100
60
70
80
90
100
mean20.out[1:1000]
0.15
n = 30
n = 50
0.0
0.0
0.05
0.04
0.10
0.08
0.12
mean10.out[1:1000]
The orange
overlay lines are
normal
distributions that
have been fit to
the histograms.
60
70
80
90
mean30.out[1:1000]
100
60
70
80
90
Stat 311 –mean50.out[1:1000]
Cardoso
100
14
14
7
Sampling Distributions (continued)
Samples from population of midterm scores. The
population has mean 𝜇 = 81.01 and standard deviation
The yellow rows of this
𝜎 = 18.34.
Sample Size
n = 10 n = 20 n = 30
Sample 1 86.89 83.05 84.45
Sample 2 77.40 73.16 82.76
Mean of
Sampling
Distribution 80.86 80.71 81.10
based on 1000
draws of size n
table show the first two
samples that were shown
n = 50 on slide 6—showing
sample means from the
82.22 midterm score population.
82.90
The last row shows the
means of the sampling
80.95 distributions for each of
the four sample sizes.
Notice how close these
means are to the true
population mean of 81.01.
15
Stat 311 – Cardoso
15
Sampling Distributions (continued)
Samples from population of midterm scores. The
population has mean 𝜇 = 81.01 and standard deviation
Sample Size
𝜎 = 18.34.
n = 10 n = 20 n = 30 n = 50
Sample 1 86.89 83.05 84.45 82.22
Sample 2 77.40 73.16 82.76 82.90
Mean of
Sampling
Distribution
based on 1000
draws of size n
80.86 80.71 81.10 80.95
SD of Sampling
Distribution
based on 1000
draws of size n
5.78
4.13
3.09
Added the light pink row
that shows the SDs for
the four sampling
distributions.
These are not close to
𝜎 = 18.34
2.36
Stat 311 – Cardoso
16
16
8
Sampling Distributions (continued)
Samples from population of midterm scores. The population
has mean 𝜇 = 81.01 and standard deviation
Sample Size
𝜎 = 18.34.
n = 10
n = 20
n = 30
n = 50
Sample 1
86.89
83.05
84.45
82.22
Sample 2
77.40
73.16
82.76
82.90
Mean of
Sampling
Distribution
based on 1000
draws of size n
SD of Sampling
Distribution
based on 1000
draws of size n
𝜎
𝑛
80.86 80.71 81.10 80.95
Now we add one last row:
the bright pink row shows
values for sigma divided by
square-root of n. Notice how
close these values are to the
light pink row.
𝜎̅
5.78
4.13
3.09
2.36
5.80
4.10
3.35
2.59
18.34
10
18.34
5.80
4.10
20
These values are close to the
sampling distributions SDs!
𝜎̅
Stat 311 – Cardoso
17
17
The “Big-5” Parameters and Their Statistics
Name
Parameter Statistic • Each of the
statistics has a
Mean
𝜇
𝑥̅
sampling
Difference between two
distribution.
means, independent
𝜇
𝜇
𝑥̅
𝑥̅
samples
• In this lecture
Difference between two
we give the
means, dependent
𝜇
𝑑̅
properties of
samples
the sampling
Proportion
𝑝
𝑝̂
distributions
for 𝑥̅ and 𝑝̂
Difference between two
proportions, independent 𝑝
𝑝
𝑝̂
𝑝̂
samples
Stat 311 – Cardoso
18
18
9
Properties of the Sampling Distribution of 𝒙
The main properties for the sampling distribution of the
mean are:
1. The mean of sampling distribution equals the mean of
sampled population: 𝜇 ̅ 𝐸 𝑥̅
𝜇
2. The standard deviation of sampling distribution equals
the standard deviation of the population divided by the
square-root of the sample size: 𝜎 ̅
3. Since the population SD, 𝜎 , is often unknown, we
define and estimate, called the standard error (SE). For
means we have: SE ̅
Stat 311 – Cardoso
19
19
Central Limit Theorem (CLT)
• Consider a random sample of n observations selected from
a population (any population) with mean, 𝜇, and
standard deviation, 𝜎.
• Then, when n is sufficiently large, the sampling
distribution of 𝑥̅ will be approximately a normal
distribution.
• We already know that the distribution of the means will
have 𝜇 ̅ 𝜇 , and standard deviation 𝜎 ̅
.
Stat 311 – Cardoso
20
20
10
CLT (continued)
• For the approximate normality we get from the CLT, it is
important to know that the larger the sample size, the
better the approximate normality for the sampling
distribution of 𝑥̅ .
• Note: if the distribution of the starting population
is normal, then the sampling distribution of 𝒙 will
be normal.
21
Stat 311 – Cardoso
21
CLT (continued)
• The sum of a random sample of 𝑛 observations, ∑
will also possess a sampling distribution that is
approximately normal for large samples.
• When working with sums we have 𝜇∑
𝜎∑
𝑛𝜎
𝑥,
𝑛𝜇 and
• How large is large? The greater the skewness of the
sampled population distribution, the larger the sample size
must be before the normal distribution is an adequate
approximation for the sampling distribution of 𝑥̅ ; for many
sampled population, sample sizes of 𝑛 30 (and sometimes
smaller) will suffice.
Stat 311 – Cardoso
22
22
11
Sampling Distribution of 𝑝
We need to know the sampling distribution of 𝑝̂
; if we were
to draw samples of size 𝑛 over and over and each time calculate
a new value of 𝑝̂ , what would the distribution look like?
Solution: view 𝑝̂ as the mean number of successes over the 𝑛
trials:
1. Assign a success a value of 1 and a failure a value of 0.
2. Define x to be the sum of all 𝑛 sample observations.
3. 𝑝̂
is the mean number of successes in 𝑛 trials.
It turns out that if X is a binomial RV, as 𝑛 → ∞ X will be
approximately normally distributed with 𝜇
𝑛𝑝
𝑛𝑝𝑞 where q = 1 – p.
and 𝜎
23
Stat 311 – Cardoso
23
Sampling Distribution for 𝒑 (continued)
What can we say about the distribution of 𝑝̂
?
𝑝̂
will also be approximately normally distributed for large
𝑛 since dividing by 𝑛 does not change the shape of the
distribution. p̂ x 1 x
n n
1
1
E p̂ E x np p
n
n
2
1 1
1
pq
2
p̂ Var x Var x 2 npq
n n
n
n
p̂
pq
n
How large is large enough? 𝒏𝒑
𝟏𝟎 𝒂𝒏𝒅 𝒏𝒒
Stat 311 – Cardoso
𝟏𝟎.
24
24
12
Properties of the Sampling Distribution of 𝒑
• Mean of sampling distribution equals mean of sampled
population (unbiased)
pˆ E pˆ p
• Standard deviation (SD) of sampling distribution
equals
p 1 p
pˆ
n
pq
n
• Standard error (SE) of sampling distribution equals
SE p̂
p̂ 1 p̂
n
p̂q̂
n
If 𝒑 is unknown, use 𝒑 and
𝒒 𝐭𝐨 𝐚𝐬𝐬𝐞𝐬𝐬 𝐬𝐚𝐦𝐩𝐥𝐞 𝐬𝐢𝐳𝐞
conditions.
Stat 311 – Cardoso
25
25
Finding Probabilities For 𝑥̅ –Example 1
A random sample of size 𝑛 25 is selected from a normal
population with mean 𝜇 106 and SD 𝜎 12.
Find 𝑃 𝑥̅ 100 .
Solution: Since the population is normal, the distribution of
𝑥̅ is normally distributed—thus, we do not need to worry about
the sample size.
12
𝑥̅ ~𝑁𝑜𝑟𝑚𝑎𝑙 106,
25
𝑃 𝑥̅
100
1 – pnorm(100,106,12/5) = 0.9937
If the mean of the population is 106, the probability that the mean
from a sample of size 25 exceeds 100 it about 99%.
Stat 311 – Cardoso
26
26
13
Plot for Sampling Distribution of 𝑥̅ , Example 1
Stat 311 – Cardoso
27
27
Finding Probabilities For 𝑥̅ –Example 2
The distribution of sales for a parts manufacturer is rightskewed and a sample of size 𝑛 15 has 𝑥̅ $10.00 and
𝑠 $2.50. Find 𝑃 𝑥̅ $11.00 .
Solution: Since the population is not normally distributed,
we need to consider the sample size—𝑛 15 is it NOT large
enough to assume that the distribution of 𝑥̅ is approximately
normally distributed. At this point we do not know how
to solve this! We will learn later in the quarter.
Assume instead that 𝑛 32. Since 𝑛 32 we can assume that
.
𝑥̅ ~𝑎𝑝𝑝𝑟𝑜𝑥 𝑁𝑜𝑟𝑚𝑎𝑙 10,
.
𝑃 𝑥̅
11
pnorm(11,10,2.5/sqrt(32)) = 0.9882
Stat 311 – Cardoso
28
28
14
Plot for Sampling Distribution of 𝑥̅ , Example 2
Stat 311 – Cardoso
29
29
Finding Probabilities For 𝒑 –Example 3
UW freshman are surveyed to determine interest in STEM
majors. 𝑛 300 students returned surveys and 170 indicated
they were interested in a STEM major. Find 𝑃 𝑝̂ 0.50 .
170
𝑝̂
0.567 ⟹ 𝑞 1 0.567 0.433
300
Solution: First check whether sample is large enough for our
methods: 𝑛𝑝̂ 300 0.567
170.1 and
𝑛𝑞 300 0.433
129.9—clearly, both are 10.
Stat 311 – Cardoso
30
30
15
Solution For 𝒑 –Example 3 (continued)
UW freshman are surveyed to determine interest in STEM
majors. 𝑛 300 students returned surveys and 170 indicated
they were interested in a STEM major. Find 𝑃 𝑝̂ 0.50 .
170
𝑝̂
0.567 ⟹ 𝑞 1 0.567 0.433
300
Solution: Since the sample size is large enough,
𝑝̂ ~approx Normal 0.567,
0.567 0.433 /300)
𝑃 𝑝̂
0.5
1- pnorm(0.5,0.567,sqrt(0.567*0.433/300))
= 0.9904
For samples of size 300, the probability of observing a sample
proportion that exceeds 0.5 is about 99%.
Stat 311 – Cardoso
31
31
Plot for Sampling Distribution of 𝑝, Example
Stat 311 – Cardoso
32
32
16
Summary—Sampling Distributions
• Individual data values may have a distribution different than
the distribution of the mean scores (based on many samples
of the same size).
• If the sample size is sufficiently large, then the Central
Limit Theorem tells us that the distribution of the sample
mean will be approximately normal.
– For skewed populations, samples with 𝑛 30 are often
sufficient, but if the original data are highly skewed, you
might need a larger sample size to assume normality.
– If the population is normally distributed, then 𝑥̅ will be
normally distributed.
33
Stat 311 – Cardoso
33
Summary—Sampling Distributions
• Large-enough for sample proportions is
𝒏𝒑
𝟏𝟎 𝐚𝐧𝐝 𝒏𝒒
𝟏𝟎
• The sampling distributions for a mean and a binomial
proportion have expected value of 𝜇 and 𝑝,
respectively.
• The standard errors of the sampling distributions for a
mean and a binomial proportion both depend on the
sample size n.
• Since the sampling distributions for 𝑥̅ and 𝑝̂ are
approximately normal when sample sizes are large
enough, you can find probabilities for values of 𝑥̅ and 𝑝̂
using software.
Stat 311 – Cardoso
34
34
17
http://www.sfu.ca/sfunews/files/summer2007/endangered.jpg
Contact me by email at tamre@uw. edu if you
have questions or comments about this lecture.
Stat 311 – Cardoso
35
35
18
Essay Writing Service Features
Our Experience
No matter how complex your assignment is, we can find the right professional for your specific task. Achiever Papers is an essay writing company that hires only the smartest minds to help you with your projects. Our expertise allows us to provide students with high-quality academic writing, editing & proofreading services.
Free Features
Free revision policy
$10Free bibliography & reference
$8Free title page
$8Free formatting
$8How Our Dissertation Writing Service Works
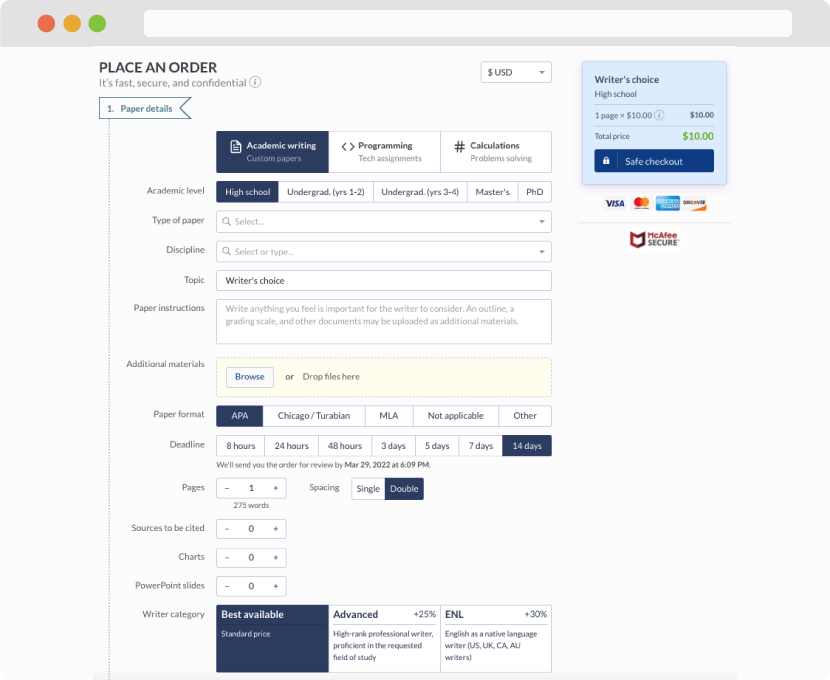
First, you will need to complete an order form. It's not difficult but, if anything is unclear, you may always chat with us so that we can guide you through it. On the order form, you will need to include some basic information concerning your order: subject, topic, number of pages, etc. We also encourage our clients to upload any relevant information or sources that will help.
Complete the order form
Once we have all the information and instructions that we need, we select the most suitable writer for your assignment. While everything seems to be clear, the writer, who has complete knowledge of the subject, may need clarification from you. It is at that point that you would receive a call or email from us.
Writer’s assignment
As soon as the writer has finished, it will be delivered both to the website and to your email address so that you will not miss it. If your deadline is close at hand, we will place a call to you to make sure that you receive the paper on time.
Completing the order and download